

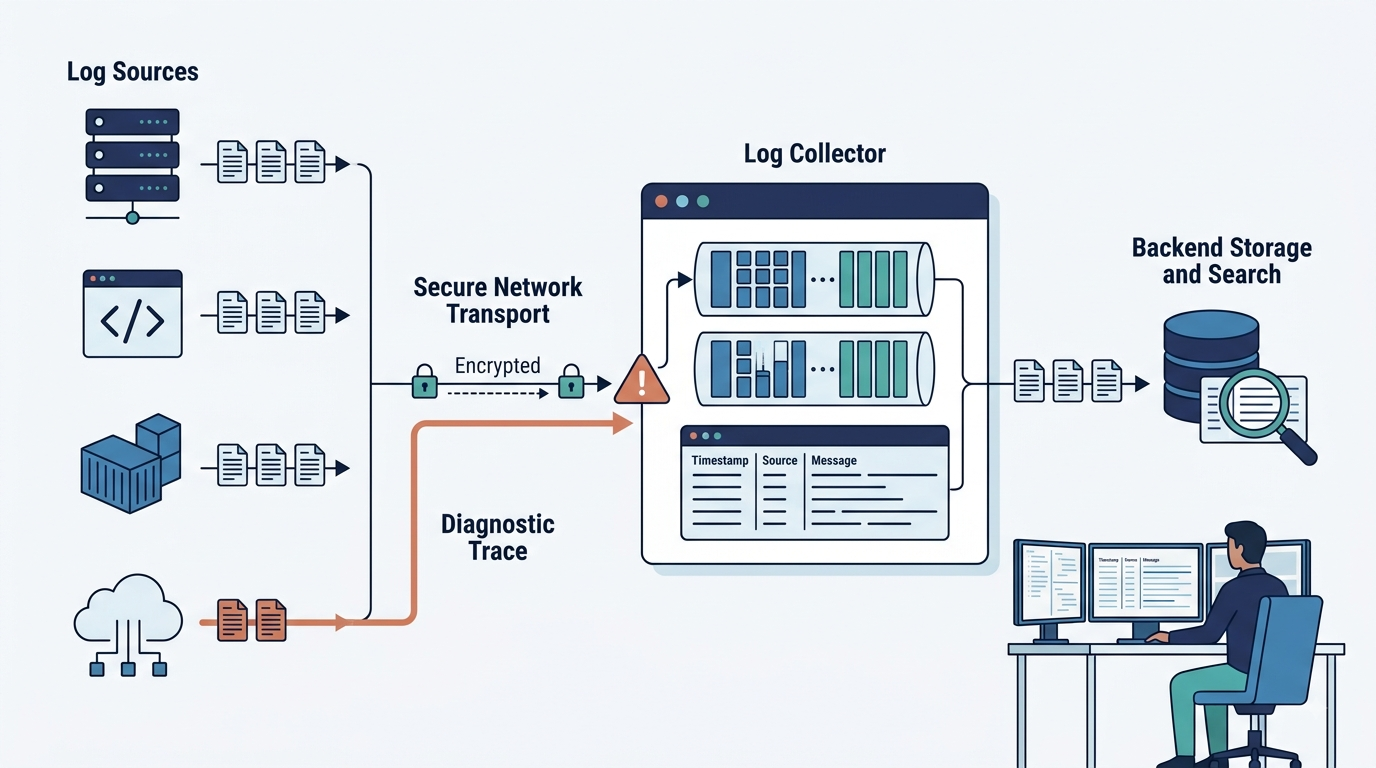
Troubleshooting log collection issues starts by finding where the log stops moving. Check the source first, then the transport path, collector, and backend. A single test event can show whether the problem comes from missing source data, agent errors, blocked connections, filters, parsing, or backend ingestion.
We use this method at MSSP Security to investigate logging problems with clear evidence instead of changing several settings at once. OpenTelemetry also recommends checking receiving, processing, exporting, configuration, and network conditions across the pipeline. Keep reading to follow the checks step by step and find the first failed handoff.
Quick Reads: Log Troubleshooting Wins
A layered approach helps you trace missing logs from the source to the backend, identify the first failed handoff, and prevent repeat collection problems.
- Trace the log pipeline layer by layer: Verify the source, transport, collector, and backend in sequence to identify the first failed handoff instead of changing multiple settings at once.
- Use one unique test event as proof: Follow a recognizable log entry from generation through collection, forwarding, ingestion, indexing, and search to separate source, agent, network, parsing, and backend failures.
- Monitor for silent failures before they become incidents: Track agent health, permissions, log rotation, queues, ingestion limits, timestamps, resource usage, and backend indexing to catch missing or delayed logs early.
What Are the Four Layers of a Log Collection Pipeline?
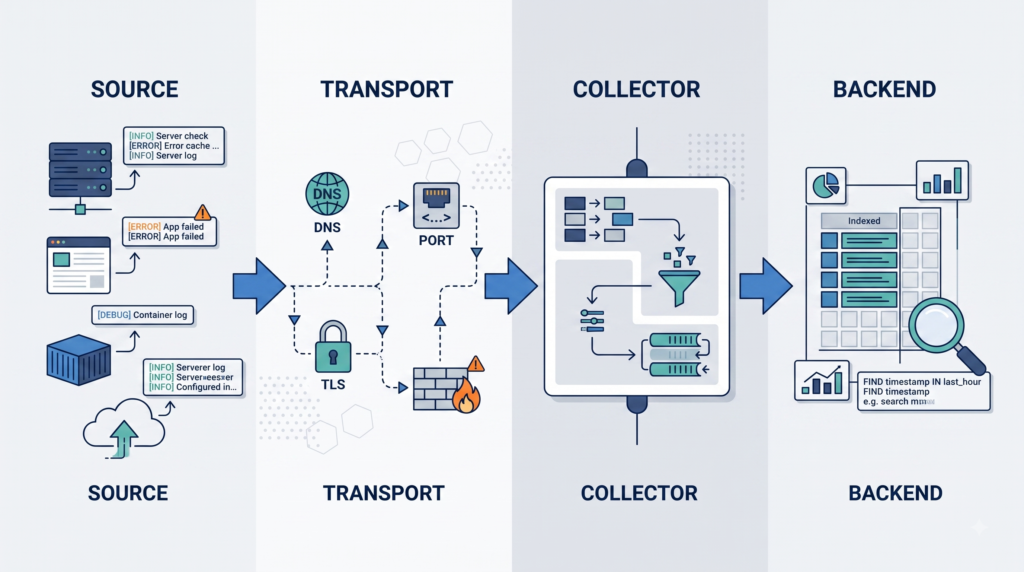
A logging pipeline has four useful layers: source, transport, collector, and backend. Each one needs its own check.
The source creates the event. Transport moves it. The collector receives and processes it. Then the backend stores and makes it available for search. A failure at any point can look like the same problem from the analyst’s side: missing logs.
| Layer | Check first | Common issue |
| Source | Event creation | Missing events |
| Transport | DNS, ports, TLS | Delivery failure |
| Collector | Status, queues | Processing errors |
| Backend | Ingestion, search | Query gaps |
We use this model during product audits because it stops teams from blaming the collector too early. A collector can show as healthy while its receiver is failing or its export queue is full.
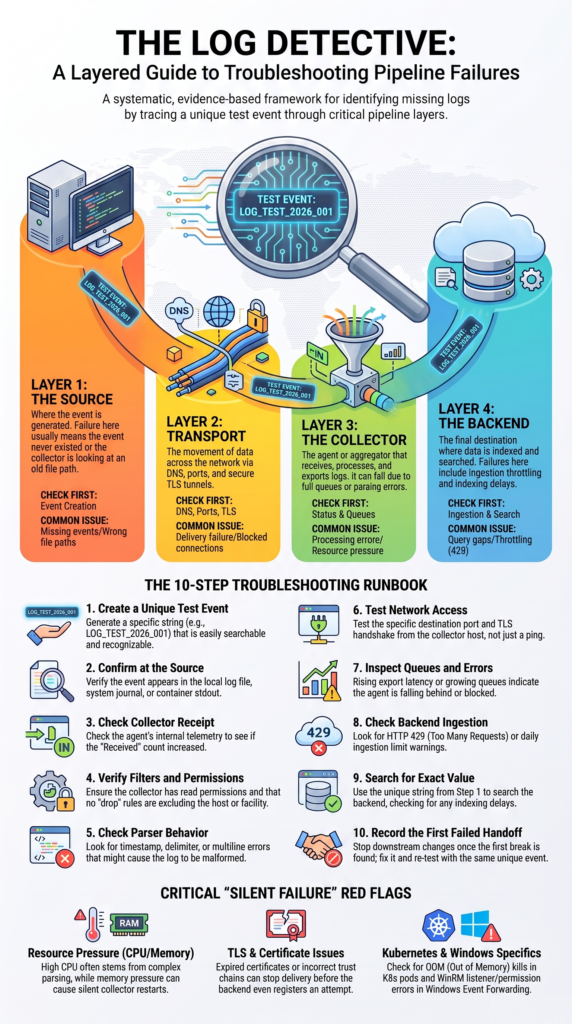
Create one unique test event. Then follow it through every layer.
- Confirm it at the source.
- Check the collector receipt.
- Verify export.
- Search for the exact value.
That gives the team something solid to track. No guessing.
Insights from Linux Professional Institute (LPI)
“The lifecycle of a log entry follows a pipeline that can be broadly divided into four stages: generation, collection, processing, and visualization.” – Linux Professional Institute (LPI)
How Can You Prove the Source Is Generating Logs?
Credits: Campbell Scientific
Check the source before changing collector settings. If the event never exists there, the collection system isn’t the first problem.
For servers, check local log files or the system journal. For applications, inspect the application’s own output. Containers need a separate check because their logs may go to standard output instead of a file.
During audits, we often create one test event with a unique value, such as LOG_TEST_2026_001. If that value appears locally but not in the backend, the source has done its job.
File paths and file lifecycles also deserve attention. A collector may point to an old directory after an application update. Permissions can change after deployment, and rotation can create a new file that the collector does not follow. Compression may also remove a file before the collector finishes reading it.
Check these items first:
- Active log path and file
- Ownership and read permissions
- Rotation and compression rules
- Raw event format
- Test event visibility
We don’t change several settings at once. One change, one test. That makes the result easier to trust.
Why Can an Agent Report Success While Logs Still Disappear?
An agent being online proves that the process is running. It does not prove that every event reaches the backend.
We start with service status, active configuration, agent logs, destination access, queues, and resource use. CPU and memory matter because a busy collector can fall behind.
A growing queue or rising export latency can show that the agent is receiving more data than it can process. When evaluating products, choosing a log collector agent for an MSSP also requires checking how well the agent exposes these health and delivery signals.
A useful health check should cover both system status and actual data flow:
- Is the process running?
- Is the source connected?
- Are events being processed?
- Are exports succeeding?
- Are queues growing?
- Is the agent under CPU or memory pressure?
Resource bottlenecks can affect different stages. High CPU may come from parsing or transformation, while memory pressure can restart the collector. Low disk space can also stop local buffering.
We don’t recommend reinstalling an agent as the first response.Compare the agent’s received, processed, queued, and exported counts when those metrics are available. That evidence separates configuration problems from capacity problems and prevents a restart from hiding the original cause.
What Should You Check When Network Transport Blocks Logs?
Test the connection from the collector itself. Check DNS, ports, routing, firewall rules, TLS, proxy settings, and authentication. These checks are also central to secure log forwarding and aggregation methods because secure transport must work reliably before logs can reach their destination.
A network problem can look like a backend problem. From the analyst’s view, both can produce the same result: no new logs. We need to know where the connection stops.
Start by resolving the destination name from the collector. Then test the required port. For HTTPS destinations, inspect the TLS connection and return status. A basic ping isn’t enough because ICMP may work while the application port stays blocked.
Our usual checks include:
- DNS resolution
- Destination port
- Firewall rules
- Proxy settings
- TLS certificates
- Authentication
- Routing
Certificate problems can be easy to miss. An expired certificate or an incorrect trust chain can stop delivery before the backend accepts anything.
During product audits, we also check whether the product gives useful connection errors. A clear error saves time during an incident. A vague “export failed” message doesn’t tell the team much.
So test from the collector, not from a laptop. The collector is the system that must make the connection.
Why Do DCRs and Filters Make Valid Logs Disappear?
Collection rules can receive valid events and then drop them because a selector, filter, transformation, or destination doesn’t match.
This is one of the harder cases to spot. The source works. The collector may also work. Yet the expected event never reaches storage.
For teams auditing new products, we check the active configuration instead of relying on the configuration shown in a planning document. Multiple rules can overlap. A selector may exclude a host, namespace, facility, severity, or stream without making the problem obvious.
A simple test event helps here. Create one that should pass every active rule. If it still disappears, move to the next layer.
| Area | Check |
| Selector | Correct source |
| Filter | Event allowed |
| Transform | Record retained |
| Destination | Correct target |
| Schema | Fields accepted |
Parsing can add another failure point. A changed timestamp, delimiter, field, or multiline format may cause a rule to stop matching.
We always compare the raw event with the expected format before changing a parser. Otherwise, a team may spend hours fixing the wrong part of the pipeline.
The active rule is what matters. Not the rule someone remembers deploying six months ago.
How Can Backend Limits Make Healthy Collectors Look Broken?
Backend limits can reject, delay, or hide events after collection has already succeeded.
This creates a frustrating situation. The collector receives the event and may report a successful export attempt, but the backend can throttle ingestion, reach a daily limit, delay indexing, or reject part of the payload. HTTP 429 responses are a clear sign that rate limiting or an ingestion policy may be involved.
Start with:
- Ingestion status
- Error responses and HTTP codes
- Throttling
- Daily or service limits
- Indexing delays
- Queue depth and retries
- Retention
We check whether the event was received before assuming it was lost. A search problem can occur when indexing has not caught up or the query uses the wrong time range.
During audits, we compare what the collector says it sent with what the backend says it received. Repeated 429 responses, growing queues, and rising export latency point to sustained pressure.
Don’t increase capacity before checking the cause. Excessive log volume, oversized batches, or unnecessary events may be driving the limit. Fix the pressure source, then retest the same unique event.
How Should You Troubleshoot Kubernetes Log Collection?
Check the workload, node collector, receiver rules, resources, and backend separately.
Kubernetes adds more places for logs to disappear. A workload may not write the expected output. A node collector may be missing. A namespace selector may exclude the workload. Memory pressure can also restart the collector.
We start at the workload. Confirm that the pod produces the expected stdout or stderr records. Then check the collector running on that node. Compare a working node with a failing one when possible.
Useful checks include:
- Pod output
- Collector status
- Restart count
- OOM events
- Namespace filters
- Receiver settings
- Internal collector telemetry
A node-by-node comparison can save time. If logs from one node arrive while another node has no data, the problem is less likely to be the backend.
Resource limits deserve attention too. A collector under memory pressure may restart before it can process its queue.
During MSSP product audits, we look at how clearly a product shows Kubernetes coverage. Teams need to know which namespaces, workloads, and nodes are actually being collected.
Don’t treat a green collector status as proof. Follow one pod’s event through the whole path. That gives the investigation a much cleaner starting point.
Which Windows Event Forwarding Failures Hide Behind “Active” Status?
An active Windows Event Forwarding subscription does not prove that events are moving correctly.
Windows forwarding depends on several pieces working together. WinRM, name resolution, permissions, subscriptions, and the forwarding service all need to line up.
We first check whether the source is creating the expected event. Then we test the connection between the source and collector. Permissions matter because the forwarding account needs access to the required event data.
Useful checks include:
- WinRM listener status
- Hostname resolution
- Source permissions
- Subscription status
- Forwarding diagnostics
- Event generation
A subscription can appear active while a source has stopped sending data.
Name resolution can cause another confusing failure. A source may resolve the collector to an unexpected address.
As noted by Microsoft Learn
“The subscription WEF-Windows-Endpoints could not be activated on target machine DESKTOP-AAA.example.com due to communication error. Error Code is 2391790808. All retries have been performed before reaching this point and so the subscription will remain inactive on this target until subscription is resubmitted / reset.” – Microsoft Learn
During an audit, we also check the quality of the diagnostic messages. Clear forwarding errors help an MSSP respond faster. Poor diagnostics turn a known failure into a long investigation.
What Is the Fastest End-to-End Log Troubleshooting Runbook?
Create one unique event and find the first point where it disappears.
This approach gives the investigation a clear boundary. We don’t need to change ten settings and hope one fixes the issue. Instead, the team follows one event from creation to search.
Use this order:
- Create a unique test event.
- Confirm it at the source.
- Check the collector receipt.
- Verify filters and permissions.
- Check parser behavior.
- Test network access.
- Inspect queues and errors.
- Check backend ingestion.
- Search for the exact value.
- Record the first failed handoff.
OpenTelemetry recommends checking collector receiving, processing, and exporting stages separately. That matches how we approach product audits. A system should make each stage visible enough for an MSSP to prove where data stopped.
Time ranges matter too. An event may exist under a different timestamp because of clock drift or processing delay.
Once the test fails at one layer, stop changing settings farther downstream. Fix the first known failure, then run the same test again. The collector layer is especially important when comparing log collector aggregator options because different architectures can handle routing, buffering, and processing in different ways.
That’s much cleaner than reinstalling agents or rebuilding pipelines without evidence.
How Can MSSPs Prevent Recurring Log Collection Incidents?
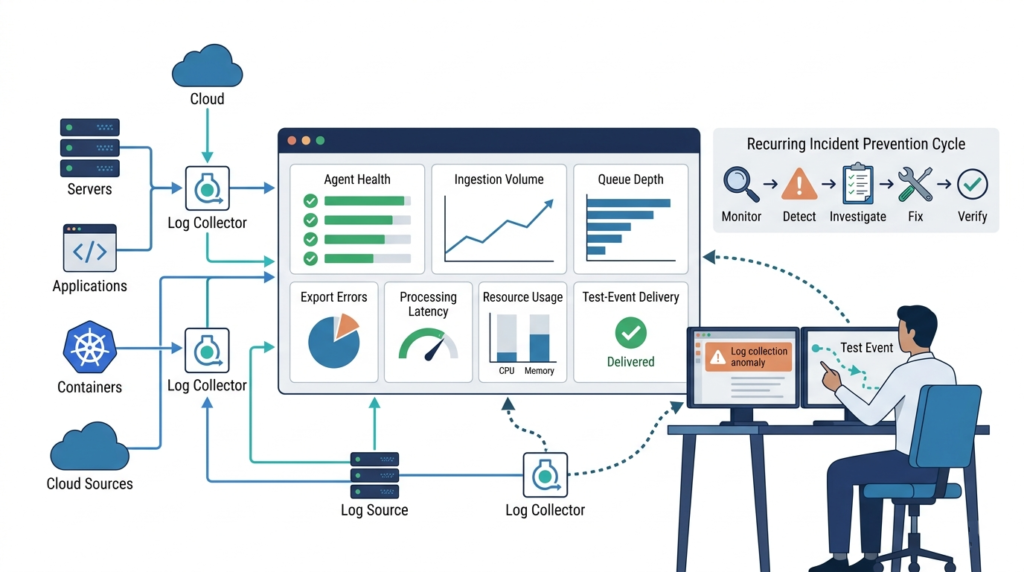
Monitor both system health and actual log delivery. An agent can be online while useful data is missing. So an MSSP needs more than heartbeat checks. It should watch ingestion volume, queue depth, export errors, processing latency, and test-event delivery.
We use this distinction during product selection and audits. A product may have a polished health dashboard, but that doesn’t mean it gives enough evidence to prove data flow.
A useful monitoring setup should cover:
- Agent health
- Ingestion volume
- Queue depth
- Export errors
- Processing latency
- Resource use
- Test events
Configuration changes should also be traceable. Version control and change records help explain when a working pipeline changed.
OpenTelemetry documents queues and persistent storage as ways to improve resilience when a destination becomes unavailable. Those features can help, but buffering needs limits. An oversized queue can create memory pressure during a long outage.
For MSSPs, the bigger question is whether a product gives operators enough control and visibility. If a platform can’t show where events are delayed or dropped, troubleshooting becomes much harder.
We’d rather identify that limitation during a product audit than during a client incident.
FAQ
How can you prevent log aggregation errors before they cause missing log entries?
Start by checking for log queue buildup, shipping delays, and incomplete log data. Set alerts when log volume changes sharply from normal levels. Review log latency and throughput during busy periods.
Test backup paths regularly to reduce the risk of data loss. A simple log collection troubleshooting routine can help teams find problems before they affect centralized logging.
What causes log normalization failures when handling unstructured log data?
Log normalization failures often occur when records use different fields, formats, or naming rules. Unstructured log data can make consistent searching and analysis difficult. Review field mappings and compare normalized records with their original events.
Check for log format parsing errors and pattern matching errors. Clear transformation rules make records easier to search, compare, and correlate.
How do timestamp synchronization issues affect log correlation across systems?
Timestamp synchronization issues can make related events appear out of order. This can make investigations harder when several systems are involved. Keep system clocks synchronized and monitor time differences regularly.
Compare event times with processing times during investigations. Accurate timestamps improve log correlation, anomaly detection, and latency monitoring when multiple services generate records during the same incident.
What should you do when log query timeouts slow down incident investigations?
First, determine whether the problem affects one query or many users. Large time ranges, complex searches, and high event volumes can slow results. Review search performance and indexing delays before changing queries.
Narrow the time range to isolate the problem. If timeouts continue, check database connections, index health, and available storage resources.
How can teams reduce log archiving issues without losing important records?
Create clear retention and archive rules based on how long records must be kept. Test archive jobs regularly and confirm that stored files can be restored. Monitor for log compression failures, storage connectivity problems, and retention policy errors.
Document recovery procedures and test them regularly. Restoration tests can reveal backup and disaster recovery failures before records are needed.
Build a Reliable Log Troubleshooting Process
When logs stop, tracing the data path from source to storage helps you find the first failed handoff instead of guessing. Test each layer with real events, then check capacity, filters, timestamps, and failure handling before changing configurations. This approach gives MSSPs clearer evidence when reviewing logging products.
A repeatable process also makes product decisions easier. For practical help with product assessment, testing, and audits, connect with MSSP Security.
References
- https://www.lpi.org/ko/blog/2026/04/21/devops-tools-introduction-14-log-management-and-analysis/
- https://learn.microsoft.com/en-in/answers/questions/5923941/windows-event-forwarding-stops-working-after-a-few